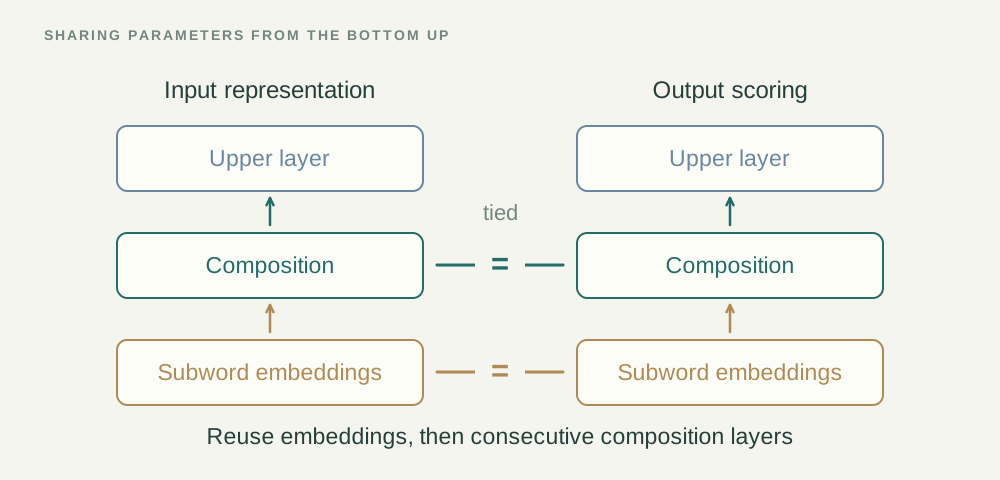
Shared subword embeddings and composition layers connect input representations with output scoring. The illustrated bottom-up tying pattern reflects the paper’s principle of reusing consecutive lower layers in a multilayer embedding model. Research source
About this paper
Explores weight sharing in subword-aware language models to reduce model size while improving selected architectures.
The study compares character-, syllable-, and morpheme-aware models. It develops a bottom-up rule for tying embedding layers and shows that suitable reuse can improve morpheme-aware models while substantially reducing their parameter counts.
Citation
BibTeX
@inproceedings{takhanov2018reusingsubwordweights,
  title = {Reusing Weights in Subword-aware Neural Language Models},
  author = {Assylbekov, Zhenisbek and Takhanov, Rustem},
  year = {2018},
  booktitle = {NAACL 2018},
  url = {https://aclanthology.org/N18-1128.pdf}
}